Loading Light/Dark Toggle

© 2026 NST LABS TECH LTD.
All Rights Reserved.

Privacy Policy
Terms of Use
Refund Policy

© 2026 NST LABS TECH LTD.
All Rights Reserved.

Disclaimer : Scrapeless strictly adheres to the laws and regulations of each region, and we do not engage in any unauthorized access or data collection from private, confidential, or restricted sources

Web Scraping Blog

Most comprehensive guide, created for all Web Scraping developers.

Most Popular Articles

loading...
Contact our sales team
Monday to Friday, 9:00 AM - 18:00 PMSingapore Standard Time (UTC+08:00)

Scrapeless offers AI-powered, robust, and scalable web scraping and automation services trusted by leading enterprises. Our enterprise-grade solutions are tailored to meet your project needs, with dedicated technical support throughout. With a strong technical team and flexible delivery times, we charge only for successful data, enabling efficient data extraction while bypassing limitations.


Contact us now to fuel your business growth.

4.8
4.5
4.8
8.5
Book a demo

Provide your contact details, and we'll promptly reach out to offer a product demo and introduction. We ensure your information remains confidential, complying with GDPR standards.

Register and Claim Free Trial

Your free trial is ready! Sign up for a Scrapeless account for free, and your trial will be instantly activated in your account.

Sign up

Latest

Scrapeless n8n Integration v0.5.4: AI Scraper Workflows
Scrapeless Official for n8n v0.5.4 adds seven AI Scraper actions. Learn how to configure them and build a multi-engine AI answer workflow.
07-Aug-2026
Scrapeless n8n AI Scraper workflow connecting seven AI answer engines to structured automation outputs.
TikTok Scraper API Guide: Profiles, Posts, and Shop Data
A practical actor guide for collecting and modeling public TikTok profile, post, and Shop product data with Scrapeless.
31-Aug-2026
TikTok scraper API workflow for profiles, posts, and Shop product data
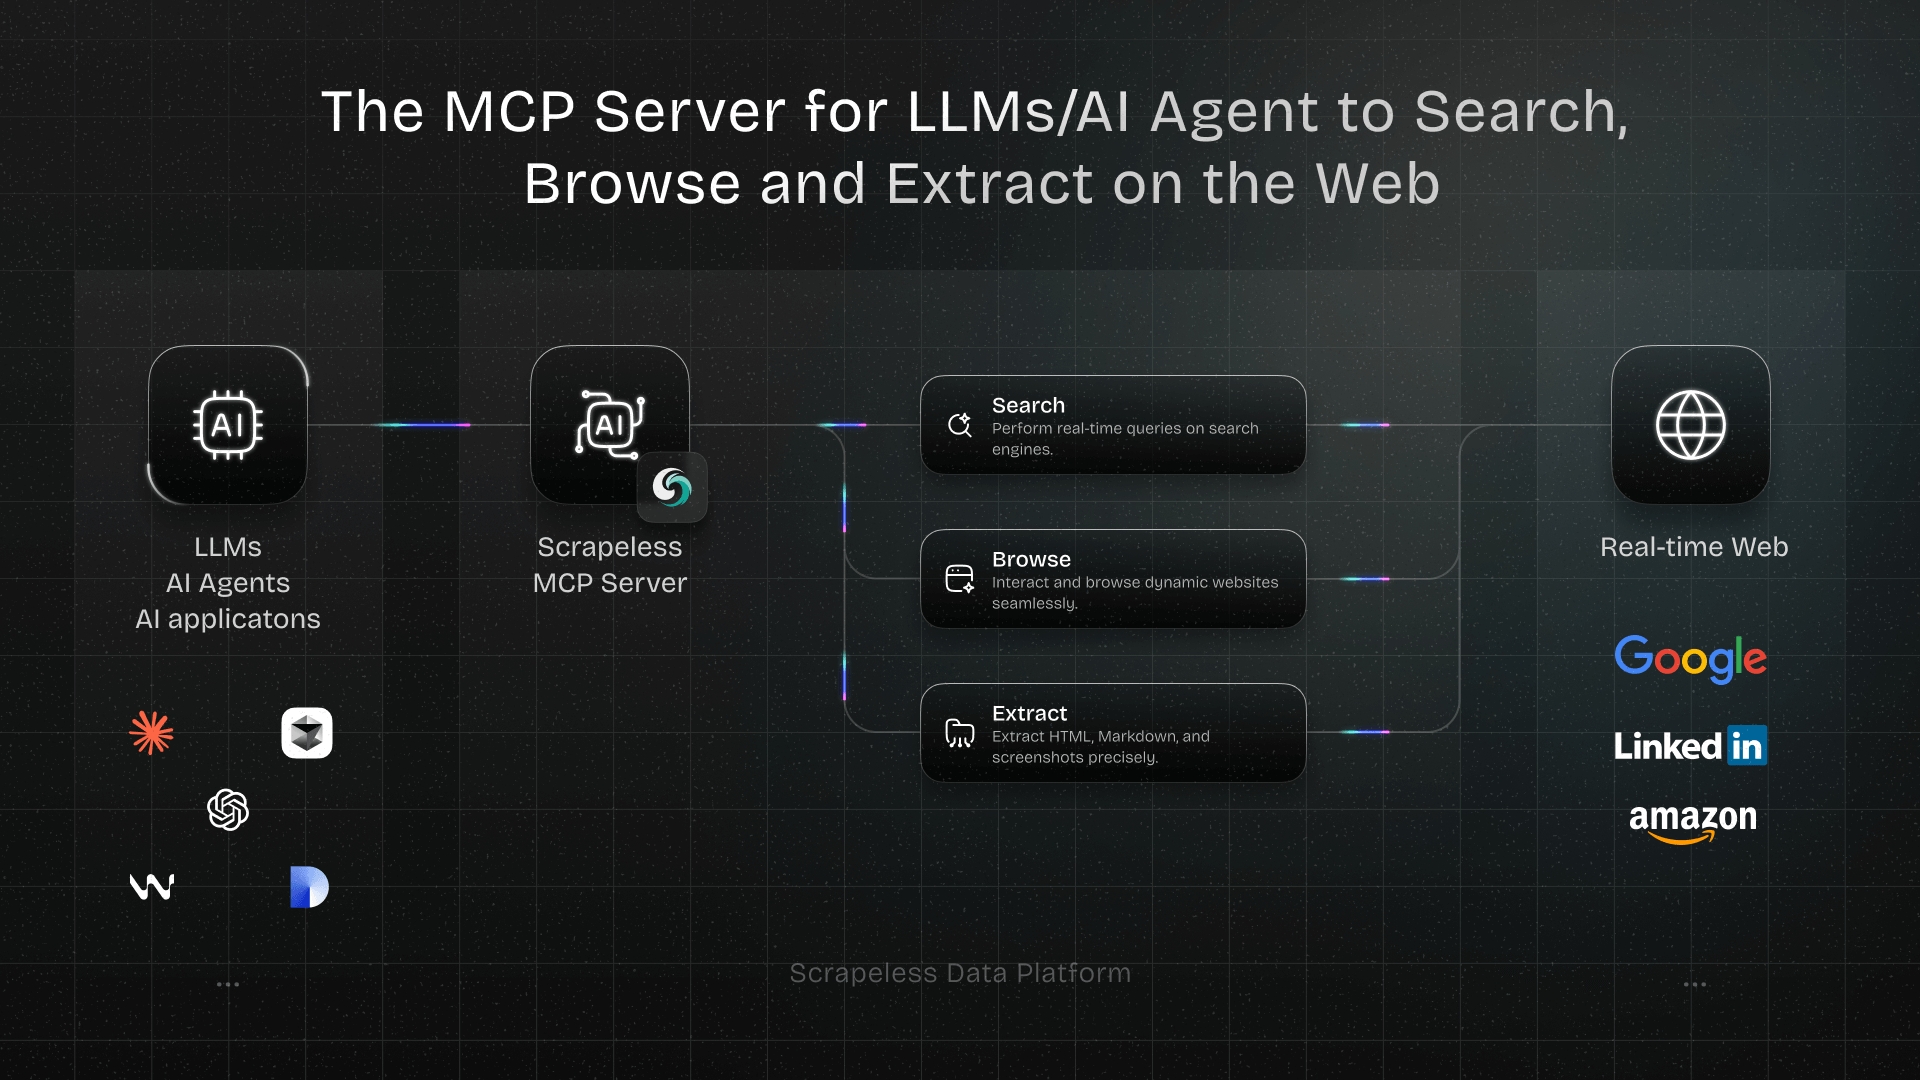
Scrapeless MCP Server Is Officially Live! Build Your Ultimate AI-Web Connector
Discover how the Scrapeless MCP Server gives LLMs real-time web browsing and scraping abilities. Learn how to build AI agents that search, extract, and interact with dynamic web content seamlessly.
17-Jul-2026
Scrapeless MCP Server

Best Zyte Alternatives in 2026

Zyte prices web scraping per website across five complexity tiers. Six alternatives — led by Scrapeless — ranked by rendering, AI-agent access, and pricing transparency.

James ThompsonJames Thompson
24-Jun-2026
Best Zyte alternatives in 2026 — web scraping API comparison cover

Scala Web Scraping: Fetch, Parse, and Unlock Protected Pages

Scala scrapes server-rendered pages with requests-scala and scala-scraper; the Universal Scraping API closes the gap on JavaScript-rendered and protected pages with one POST.

Ava WilsonAva Wilson
23-Jun-2026
Scala web scraping with Scrapeless Universal Scraping API

Best Google Maps Extractors in 2026

A ranked look at the best Google Maps extractors in 2026 and where a cloud Scraping Browser fits.

Ava WilsonAva Wilson
18-Jun-2026
Best Google Maps Extractors in 2026

How to Monitor Amazon Rufus Recommendations Over Time

Build a pipeline that captures Amazon Rufus recommendations for a query set, extracts ASINs and ranks, and diffs snapshots over time for share-of-recommendation.

Michael LeeMichael Lee
17-Jun-2026
Pipeline tracking Amazon Rufus product recommendations over time

Web Scraping with JavaScript and Node.js: Cheerio vs Puppeteer

Web scraping with JavaScript and Node.js comes down to a single early call — is the data in the HTML, or built by JavaScript? Cheerio handles the first case at parser speed; Puppeteer handles the second by rendering the page. Running both on Scrapeless Scraping Browser means the fetch succeeds either way, with residential egress and anti-detection underneath. For a deeper anti-bot workflow, see the Scrapling + Scrapeless guide; the Scraping Browser product page and docs cover the full SDK surface. Check the raw HTML first, reach for Cheerio when you can and Puppeteer when you must, and wait on content not the clock.

Daniel KimDaniel Kim
15-Jun-2026
Web Scraping with JavaScript and Node.js: Cheerio vs Puppeteer

TikTok Scraper 2026: Solving Anti-Bot & Hydration Challenges with Scrapeless

This article explains a dual-read approach to scraping TikTok, combining the extraction of in-page rehydration JSON with the capture of scroll-triggered XHR responses. It concludes that by using the Scrapeless Scraping Browser with residential proxies and anti-detection features, developers can reliably bypass TikTok’s aggressive fingerprinting to collect high-fidelity social data for creator analysis and market research.

Emily ChenEmily Chen
15-Jun-2026
TikTok Scraper 2026: Solving Anti-Bot & Hydration Challenges with Scrapeless

How to Scrape Qwen AI Answers With the Scrapeless Scraping Browser

This article provides a comprehensive technical walkthrough on using the Scrapeless Scraping Browser to automate data extraction from Qwen Studio, overcoming challenges like JavaScript rendering and token-by-token streaming. It explains how to programmatically drive the chat interface to capture structured answers and reasoning traces, concluding that this approach is essential for building reliable AI evaluation datasets and real-time brand monitoring pipelines.

Daniel KimDaniel Kim
10-Jun-2026
Scraping Qwen AI chat answers with the Scrapeless Scraping Browser

Google Local Scraper API: Turn the Local Pack into JSON

The Scrapeless Scraper API turns the Google local pack into a single POST against the scraper.google.search actor. Send tbm: "lcl" and you get map-backed business listings — titles, ratings, reviews, and addresses — as structured JSON.

Isabella GarciaIsabella Garcia
10-Jun-2026
Google Local pack returned as parsed JSON
Previous
42
43
44
Next