Loading Light/Dark Toggle

© 2026 NST LABS TECH LTD.
All Rights Reserved.

Privacy Policy
Terms of Use
Refund Policy

© 2026 NST LABS TECH LTD.
All Rights Reserved.

Disclaimer : Scrapeless strictly adheres to the laws and regulations of each region, and we do not engage in any unauthorized access or data collection from private, confidential, or restricted sources

Web Scraping Blog

Most comprehensive guide, created for all Web Scraping developers.

Contact our sales team
Monday to Friday, 9:00 AM - 18:00 PMSingapore Standard Time (UTC+08:00)

Scrapeless offers AI-powered, robust, and scalable web scraping and automation services trusted by leading enterprises. Our enterprise-grade solutions are tailored to meet your project needs, with dedicated technical support throughout. With a strong technical team and flexible delivery times, we charge only for successful data, enabling efficient data extraction while bypassing limitations.


Contact us now to fuel your business growth.

4.8
4.5
4.8
8.5
Book a demo

Provide your contact details, and we'll promptly reach out to offer a product demo and introduction. We ensure your information remains confidential, complying with GDPR standards.

Register and Claim Free Trial

Your free trial is ready! Sign up for a Scrapeless account for free, and your trial will be instantly activated in your account.

Sign up

Most Popular Articles

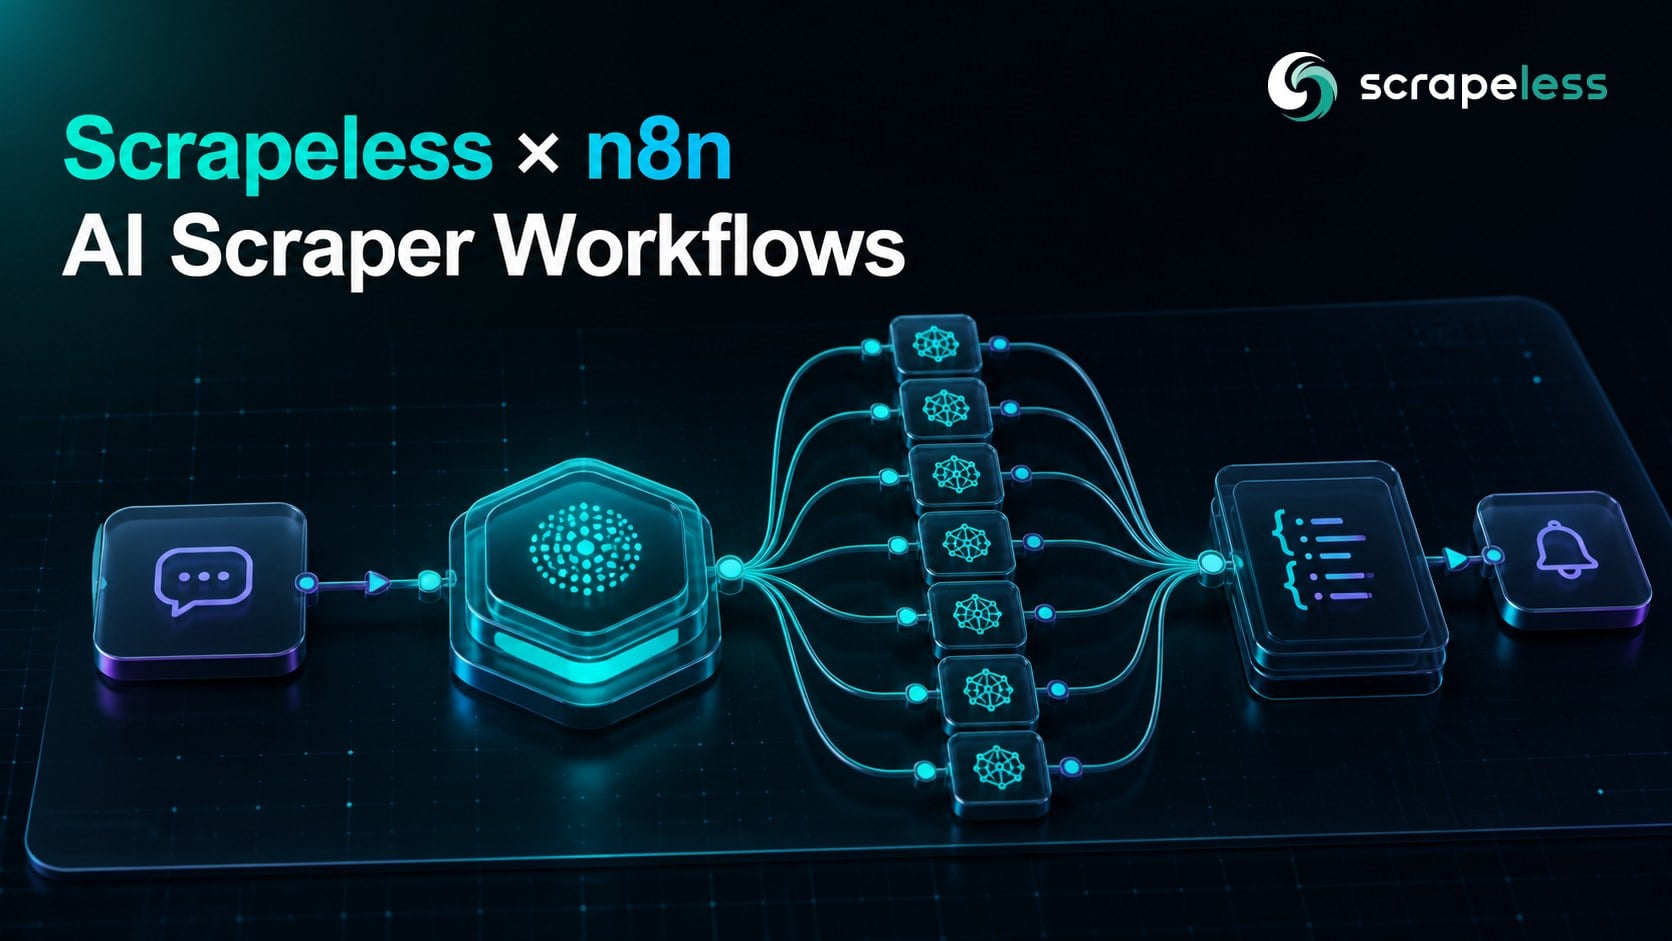
Scrapeless n8n Integration v0.5.4: AI Scraper Workflows
Scrapeless Official for n8n v0.5.4 adds seven AI Scraper actions. Learn how to configure them and build a multi-engine AI answer workflow.
07-Aug-2026
Scrapeless n8n AI Scraper workflow connecting seven AI answer engines to structured automation outputs.
TikTok Scraper API Guide: Profiles, Posts, and Shop Data
A practical actor guide for collecting and modeling public TikTok profile, post, and Shop product data with Scrapeless.
31-Aug-2026
TikTok scraper API workflow for profiles, posts, and Shop product data
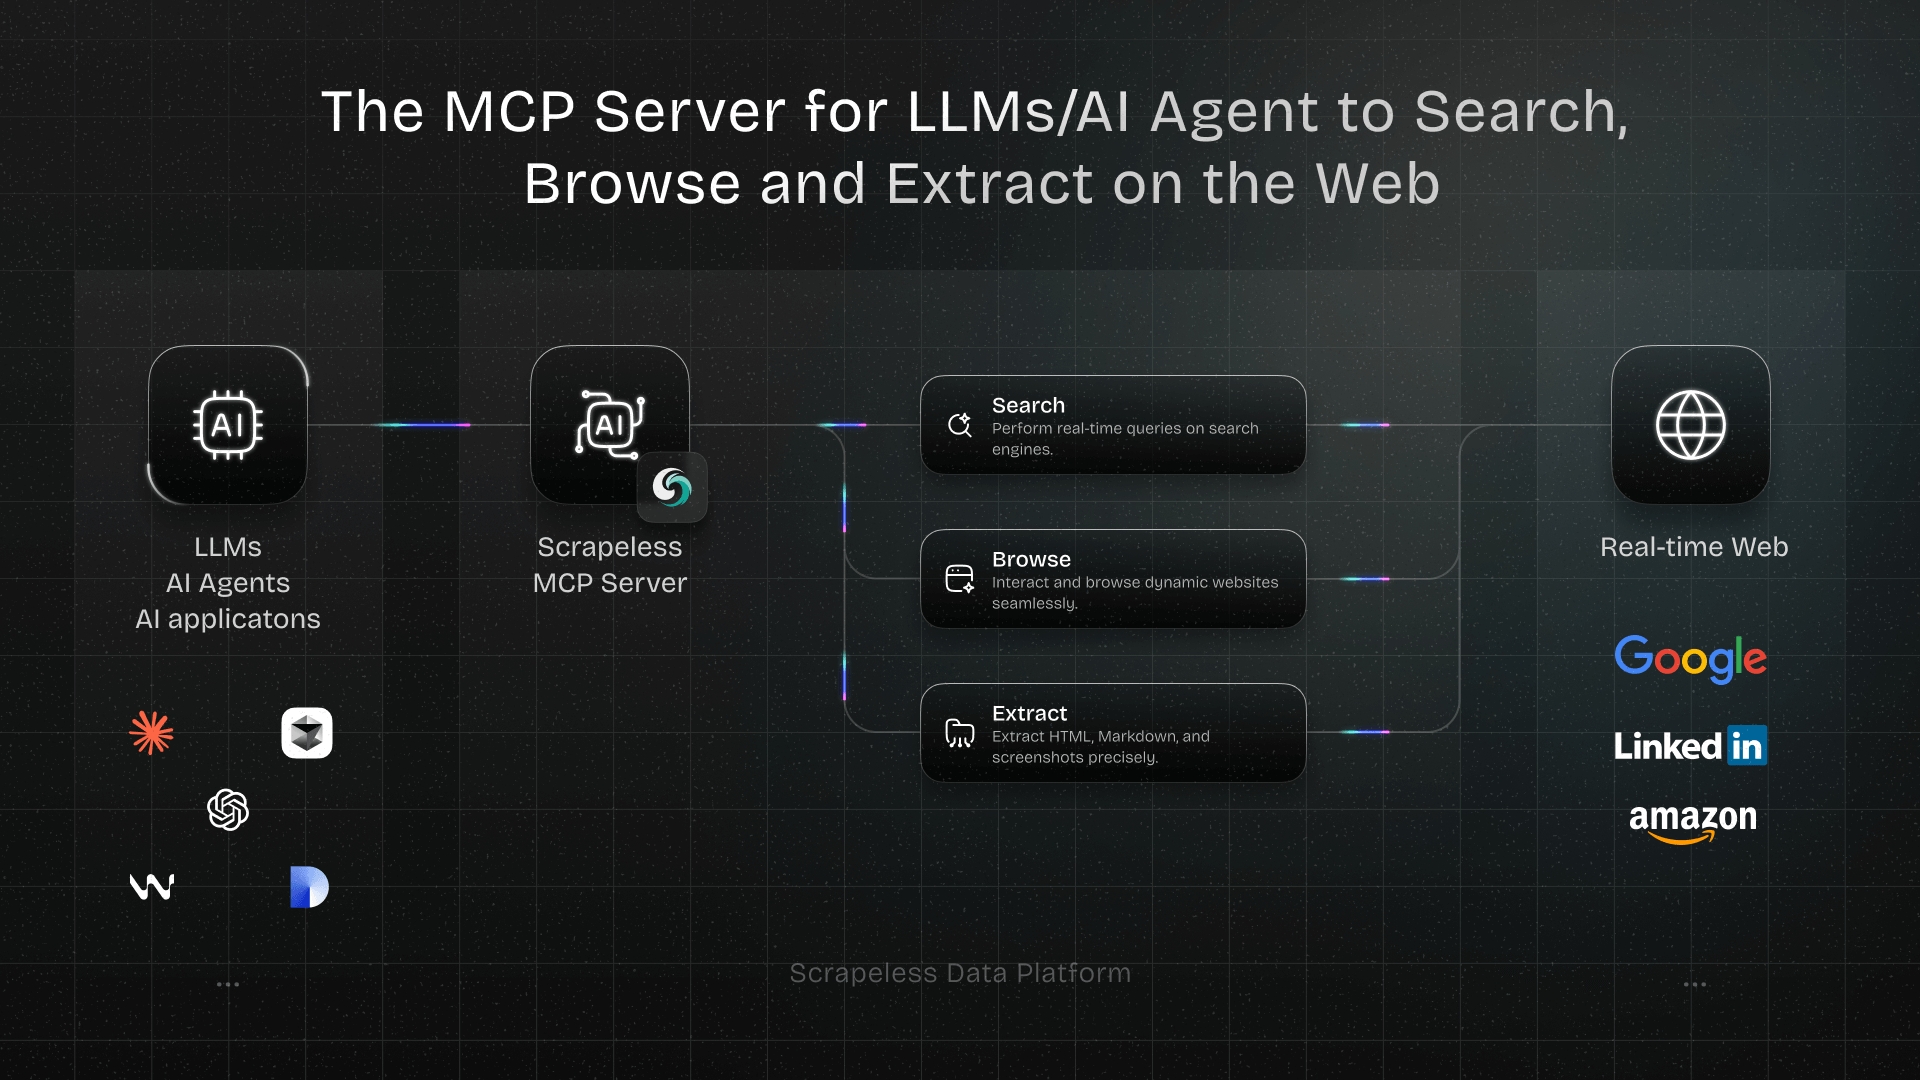
Scrapeless MCP Server Is Officially Live! Build Your Ultimate AI-Web Connector
Discover how the Scrapeless MCP Server gives LLMs real-time web browsing and scraping abilities. Learn how to build AI agents that search, extract, and interact with dynamic web content seamlessly.
17-Jul-2026
Scrapeless MCP Server
loading...

Latest

Top LLM Scrapers for 2026: Essential AI Answer Scraping Tools for Brand Visibility

This article evaluates six leading LLM (Large Language Model) scraping tools, defining their purpose and assessing them against key criteria such as interface, model coverage, and data depth, to address the critical need for monitoring brand visibility in the evolving landscape of AI-generated search answers. It concludes that tools like Scrapeless, which provide structured, citation-aware AI answer capture, are essential for effective Generative Engine Optimization (GEO) and competitive intelligence in the era of AI-powered search.

Emily ChenEmily Chen
08-Jun-2026
Top LLM Scrapers for 2026: Essential AI Answer Scraping Tools for Brand Visibility

How to Enable Mastra AI Agents with Real-Time Web Access Ability

This article demonstrates how to integrate the Scrapeless MCP server with the Mastra TypeScript framework, providing AI agents with real-time web access capabilities. It explains the seamless connection of 21 powerful web scraping and browser automation tools, concluding that this integration significantly enhances Mastra agents' ability to perform dynamic web interactions and overcome modern web challenges through natural language prompts.

Daniel KimDaniel Kim
04-Jun-2026
How to Enable Mastra AI Agents with Real-Time Web Access Ability

Data-Driven Recruitment: Building a Scalable Talent Intelligence Platform via Web Scraping

This article details the architecture and implementation of a talent market intelligence pipeline, leveraging the Scrapeless Scraping Browser to extract firmographic hiring signals from public web sources. It explains how to overcome modern web scraping challenges and process this data into actionable insights like hiring velocity and backfill pressure, while strictly adhering to data privacy and compliance by focusing solely on company- and role-level information.

Michael LeeMichael Lee
04-Jun-2026
Data-Driven Recruitment: Building a Scalable Talent Intelligence Platform via Web Scraping

Real-Time Review Monitoring Pipeline: Leveraging AI for Customer Feedback

This article details the construction of a robust review monitoring pipeline using the Scrapeless Scraping Browser, addressing the technical challenges of collecting dynamic online review data at scale. It explains a five-stage workflow—collect, normalize, analyze, store, and alert—to transform scattered customer feedback into actionable insights, ultimately enabling businesses to proactively detect and respond to negative sentiment spikes.

Ethan BrownEthan Brown
04-Jun-2026
Real-Time Review Monitoring Pipeline: Leveraging AI for Customer Feedback

Powering AI Agents: A Guide to Live Web Data Acquisition & Scraping Best Practices

This article highlights that the true bottleneck for AI agents often lies in acquiring fresh, accurate web data, rather than the AI models' reasoning capabilities, due to modern web complexities like JavaScript rendering and anti-bot measures. It then introduces Scrapeless as an agent-native solution, providing a cloud browser and MCP tools that overcome these challenges, enabling AI agents to effectively access and utilize real-time web information across diverse applications by meeting critical success criteria for web data tools.

Ethan BrownEthan Brown
04-Jun-2026
Powering AI Agents: A Guide to Live Web Data Acquisition & Scraping Best Practices

From Sitemaps to Rendered Links: The 6-Method Stack for Full-Site URL Discovery

This guide demonstrates that no single method returns a complete URL inventory—Google's site: operator gives a fast estimate, sitemaps declare what publishers registered, a breadth-first HTTP crawler finds linked orphans, and a cloud browser renders JavaScript-painted links—and walks through six methods in order of cost and completeness, from the free site: search to the full-stack approach: read robots.txt for sitemap locations and disallow rules, walk the sitemap tree recursively, run a Python BFS crawler that honors robots.txt on every URL, and escalate JavaScript-heavy hosts to Scrapeless Scraping Browser for client-side link discovery. The result is a layered, de-duplicated union that covers technical SEO audits, content migrations, broken-link sweeps, price monitoring, LLM corpus ingestion, and competitive content mapping—proving that complete URL discovery requires treating sitemaps, crawlers, and rendering as complementary methods, not alternatives."

Ava WilsonAva Wilson
03-Jun-2026
From Sitemaps to Rendered Links: The 6-Method Stack for Full-Site URL Discovery

From Free to Metered: How Pay-Per-Crawl Changes Data Team Economics

This guide argues that 'free' public data was never free but unmetered—the open web ran on an implicit bargain where crawlers took content and publishers got referral traffic in return, a bargain that AI answer engines broke by reading pages without sending clicks—and that pay-per-crawl (implemented via HTTP 402 and Cloudflare's infrastructure) represents the market repricing what that read is worth, shifting data costs from infrastructure (proxies, rendering, engineering) to access fees. The operational fix is not philosophical but disciplined: separate discovery (broad, low-frequency mapping) from refresh (narrow, high-frequency updates), track cost per usable update instead of cost per request, and invest in clean renders that succeed on the first attempt, so a data team pays each access charge exactly once and the metered web becomes a solvable economics problem rather than a budget catastrophe.

James ThompsonJames Thompson
03-Jun-2026
From Free to Metered: How Pay-Per-Crawl Changes Data Team Economics

Why Your Elixir Scraper Gets Blocked, And How Residential Proxies + Cloud Browser Fix It

This guide demonstrates that Elixir's BEAM runtime enables cheap concurrency for web scraping—spawning thousands of lightweight processes to fan out across URLs without thread-pool tuning—and pairs this native concurrency with a two-tier escalation pattern: the HTTP tier uses Req, HTTPoison, and Crawly routed through Scrapeless residential proxies in 195+ countries for server-rendered pages, while the browser tier escalates JavaScript-heavy and anti-bot targets to the Scrapeless Scraping Browser through a minimal Python rendering helper called from Elixir via System.cmd/3. The result is a production-grade scraping stack that handles concurrent catalogue crawls, scheduled monitoring, geo-specific snapshots, and RAG ingestion at startup scale—all without asking the BEAM to speak Chrome DevTools Protocol directly.

James ThompsonJames Thompson
03-Jun-2026
Why Your Elixir Scraper Gets Blocked, And How Residential Proxies + Cloud Browser Fix It
Previous
44
45
46
Next