Loading Light/Dark Toggle

© 2026 NST LABS TECH LTD.
All Rights Reserved.

Privacy Policy
Terms of Use
Refund Policy

© 2026 NST LABS TECH LTD.
All Rights Reserved.

Disclaimer : Scrapeless strictly adheres to the laws and regulations of each region, and we do not engage in any unauthorized access or data collection from private, confidential, or restricted sources

Web Scraping Blog

Most comprehensive guide, created for all Web Scraping developers.

Contact our sales team
Monday to Friday, 9:00 AM - 18:00 PMSingapore Standard Time (UTC+08:00)

Scrapeless offers AI-powered, robust, and scalable web scraping and automation services trusted by leading enterprises. Our enterprise-grade solutions are tailored to meet your project needs, with dedicated technical support throughout. With a strong technical team and flexible delivery times, we charge only for successful data, enabling efficient data extraction while bypassing limitations.


Contact us now to fuel your business growth.

4.8
4.5
4.8
8.5
Book a demo

Provide your contact details, and we'll promptly reach out to offer a product demo and introduction. We ensure your information remains confidential, complying with GDPR standards.

Register and Claim Free Trial

Your free trial is ready! Sign up for a Scrapeless account for free, and your trial will be instantly activated in your account.

Sign up

Most Popular Articles

Scrapeless n8n Integration v0.5.4: AI Scraper Workflows
Scrapeless Official for n8n v0.5.4 adds seven AI Scraper actions. Learn how to configure them and build a multi-engine AI answer workflow.
07-Aug-2026
Scrapeless n8n AI Scraper workflow connecting seven AI answer engines to structured automation outputs.
TikTok Scraper API Guide: Profiles, Posts, and Shop Data
A practical actor guide for collecting and modeling public TikTok profile, post, and Shop product data with Scrapeless.
31-Aug-2026
TikTok scraper API workflow for profiles, posts, and Shop product data
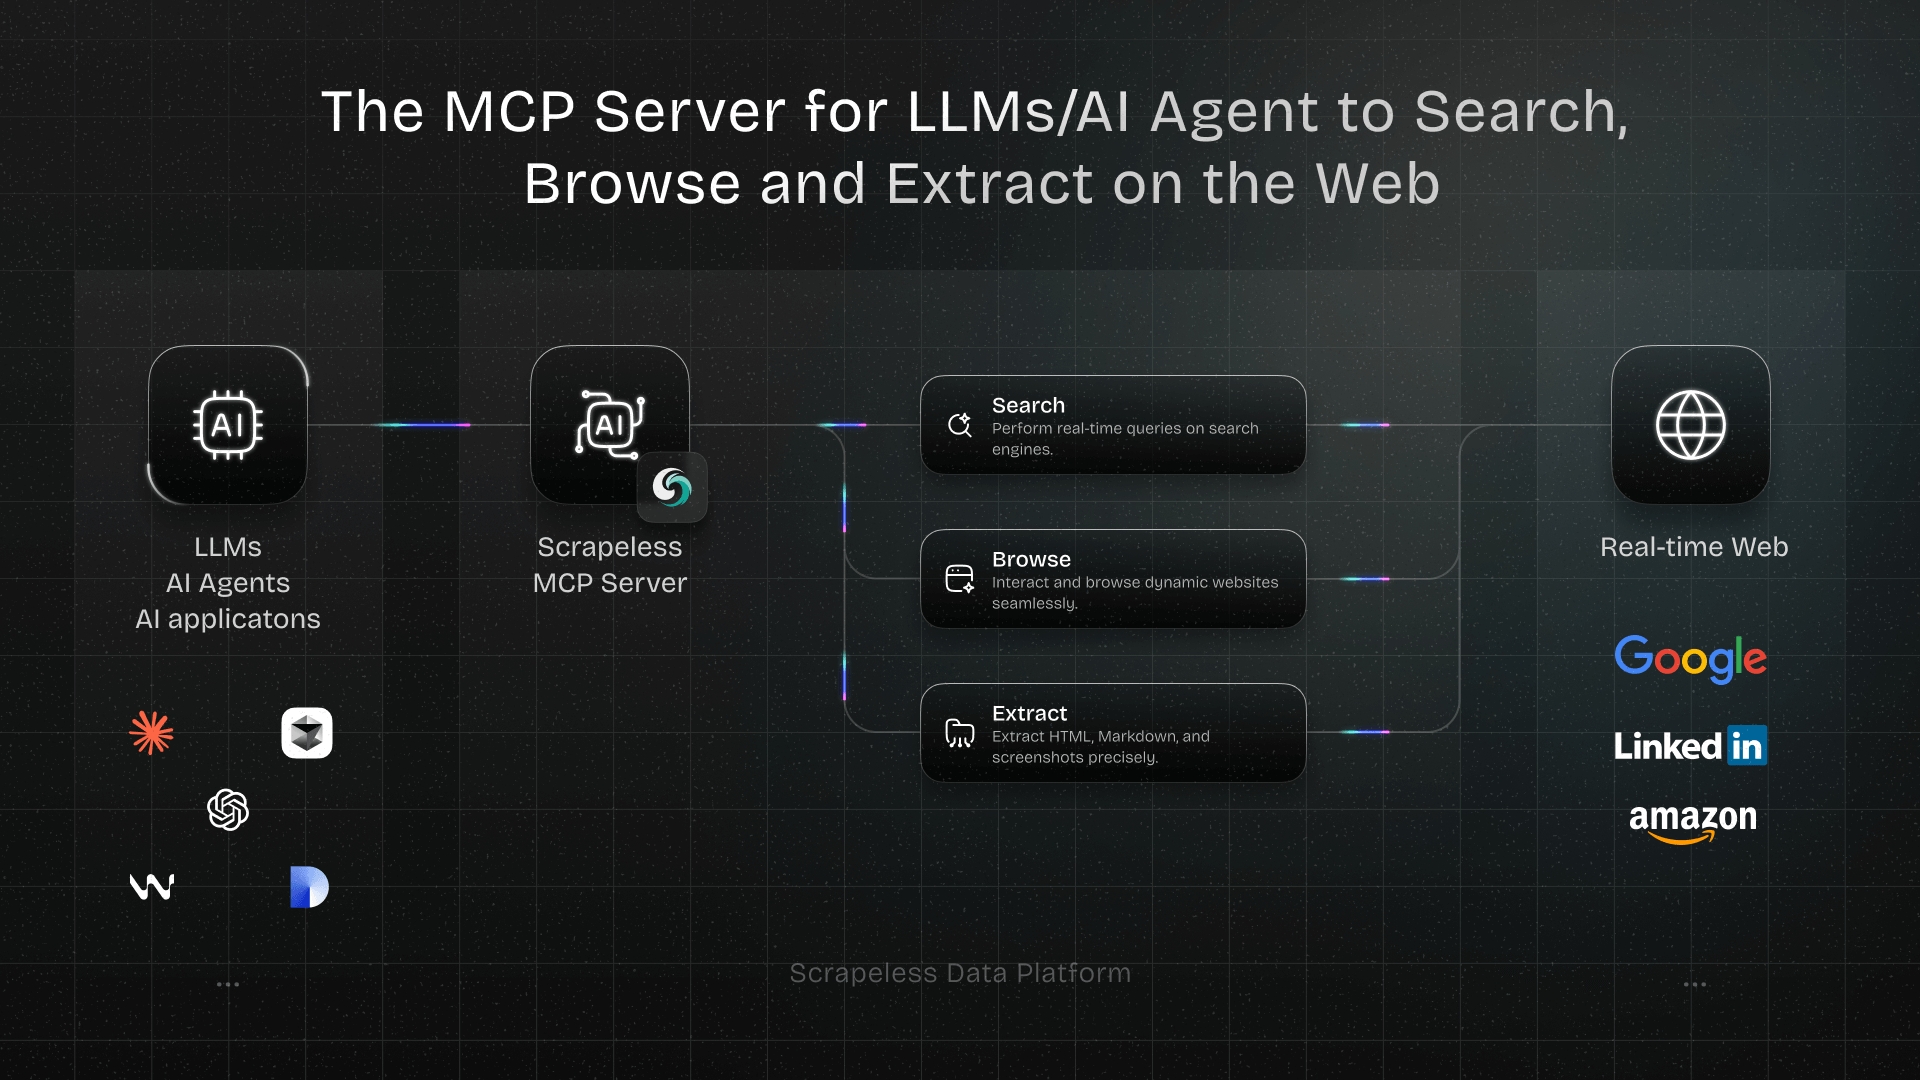
Scrapeless MCP Server Is Officially Live! Build Your Ultimate AI-Web Connector
Discover how the Scrapeless MCP Server gives LLMs real-time web browsing and scraping abilities. Learn how to build AI agents that search, extract, and interact with dynamic web content seamlessly.
17-Jul-2026
Scrapeless MCP Server
loading...

Latest

Data Access Inequality: Why Your Competitors See Markets You Cannot

Public data is open in theory and gated in practice: reading one page is trivial, but reading ten thousand pages a day from forty countries behind JavaScript and anti-bot defenses is an infrastructure problem. This gap between who can do that at scale and who cannot—not the data itself—is where competitive advantage concentrates, and AI systems inherit and amplify it. The solution is infrastructure (residential proxies across 195+ countries, anti-detection cloud rendering, unified API surface) that turns 'public in principle' into 'reachable in practice' for small teams, used responsibly to level the field without trampling it.

Michael LeeMichael Lee
03-Jun-2026
Data Access Inequality: Why Your Competitors See Markets You Cannot

The AI Economy Stack: How Autonomous Agents Are Reshaping Commerce and the Web

This guide walks through the three-layer AI economy stack that powers agentic commerce—a tool protocol (MCP) that lets agents reach tools and data, machine-native payment protocols (x402, Agentic Commerce Protocol, Agent Payments Protocol) that let agents settle value without a human, and a reliable data layer that keeps autonomous purchase decisions grounded in what is actually true on the live web. The critical insight is that data quality is the load-bearing foundation: an agent that pays on a stale price or an empty JavaScript-rendered page fails silently and expensively, which is why the Scrapeless Scraping Browser—rendering JavaScript, pinning residential egress by region, and defeating anti-bot systems—is not a nice-to-have but a must-have for any agentic-commerce system that wants to reach the majority of the web that is still built for humans.

Emily ChenEmily Chen
03-Jun-2026
The AI Economy Stack: How Autonomous Agents Are Reshaping Commerce and the Web

How to Build Production-Grade RAG Systems and Reduce LLM Token Costs by 70%

This guide demonstrates that building high-quality LLM and RAG corpora requires clean text extraction, not raw HTML, and walks through a four-stage Python pipeline—discover URLs via google_search or sitemaps, render each page in an anti-detection cloud browser and extract clean Markdown with scrape_markdown, chunk the Markdown into 500–1000-token overlapping windows, and embed each chunk into a vector database for retrieval. The result is a scalable system that turns messy public web pages into production-grade corpora with 70% lower token costs and dramatically better retrieval quality, all without per-site adapters or fingerprint tuning.

Ethan BrownEthan Brown
02-Jun-2026
How to Build Production-Grade RAG Systems and Reduce LLM Token Costs by 70%

How to Turn Google Maps Into a Lead Pipeline: Extract 1000s of Qualified Prospects in Hours

Google Maps holds the richest local business directory, but extracting it at scale requires anti-detection rendering and residential proxy routing. This guide walks through a four-stage workflow—discover with google_search and rendered Maps scrolling, extract structured fields from semantic selectors, enrich from business websites, and qualify by reputation—that turns category searches into deduplicated, CRM-ready lead lists without manual research or per-site adapters.

Isabella GarciaIsabella Garcia
02-Jun-2026
How to Turn Google Maps Into a Lead Pipeline: Extract 1000s of Qualified Prospects in Hours

How to Send JSON with cURL: Complete Guide to -d, --json, and Common Mistakes

This guide demonstrates that sending JSON with cURL requires two independent components—a JSON request body and a Content-Type: application/json header—and walks through the two methods to achieve this: the classic -d flag plus explicit -H header, and the modern --json shortcut (curl 7.82.0+) that sets both headers automatically. By covering common mistakes (shell quoting, forgetting headers, file handling), worked examples against public echo endpoints, and a real call to the Scrapeless MCP API, the guide shows how a curl command that works in your terminal translates directly into production code.

Sophia MartinezSophia Martinez
02-Jun-2026
How to Send JSON with cURL: Complete Guide to -d, --json, and Common Mistakes

How to Build a Price-Drop Alert in Python: Real-Time Monitoring with Scrapeless Scraping Browser

This guide demonstrates how to build a production-grade price-drop alert system by combining Scrapeless Scraping Browser's anti-detection cloud rendering with a simple Python pipeline that extracts prices from the populated DOM, stores them in an append-only log, compares against the previous low, and fires webhooks on drops. The result is a scalable monitoring system that works across most public product pages, handles regional pricing variations through geo-pinned proxies, and runs unattended on any scheduler—proving that real-time price tracking requires rendering, not just HTTP requests.

Ethan BrownEthan Brown
01-Jun-2026
How to Build a Price-Drop Alert in Python: Real-Time Monitoring with Scrapeless Scraping Browser

How to Scrape Walmart Product Data: Why Generic Proxies Fail and What Actually Works

This guide shows you how to reliably extract Walmart product data, competitive pricing, and inventory information without hitting anti-bot walls or getting bot-check pages disguised as HTTP 200 responses. Learn why generic proxies fail on Walmart, and discover how rendered cloud browsers with residential egress and session persistence deliver the actual product grid you need for price tracking, MAP compliance monitoring, and catalog ingestion at scale.

Ethan BrownEthan Brown
01-Jun-2026
How to Scrape Walmart Product Data: Why Generic Proxies Fail and What Actually Works

How to Scrape eBay Search Results: Session Warm-Up and Anti-Detection Guide

This guide walks through the session warm-up pattern that bypasses eBay's search endpoint protections, so you can collect pricing and availability data reliably and feed it into repricing rules, brand-protection workflows, or AI-powered product research. Build a production-grade eBay monitoring pipeline that tracks competitor prices, detects unauthorized listings, and captures geo-specific product data—all without hitting eBay's anti-detection walls.

Emily ChenEmily Chen
01-Jun-2026
How to Scrape eBay Search Results: Session Warm-Up and Anti-Detection Guide
Previous
45
46
47
Next