Loading Light/Dark Toggle

© 2026 NST LABS TECH LTD.
All Rights Reserved.

Privacy Policy
Terms of Use
Refund Policy

© 2026 NST LABS TECH LTD.
All Rights Reserved.

Disclaimer : Scrapeless strictly adheres to the laws and regulations of each region, and we do not engage in any unauthorized access or data collection from private, confidential, or restricted sources

Web Scraping Blog

Most comprehensive guide, created for all Web Scraping developers.

Most Popular Articles

loading...
Contact our sales team
Monday to Friday, 9:00 AM - 18:00 PMSingapore Standard Time (UTC+08:00)

Scrapeless offers AI-powered, robust, and scalable web scraping and automation services trusted by leading enterprises. Our enterprise-grade solutions are tailored to meet your project needs, with dedicated technical support throughout. With a strong technical team and flexible delivery times, we charge only for successful data, enabling efficient data extraction while bypassing limitations.


Contact us now to fuel your business growth.

4.8
4.5
4.8
8.5
Book a demo

Provide your contact details, and we'll promptly reach out to offer a product demo and introduction. We ensure your information remains confidential, complying with GDPR standards.

Register and Claim Free Trial

Your free trial is ready! Sign up for a Scrapeless account for free, and your trial will be instantly activated in your account.

Sign up

Latest

Scrapeless n8n Integration v0.5.4: AI Scraper Workflows
Scrapeless Official for n8n v0.5.4 adds seven AI Scraper actions. Learn how to configure them and build a multi-engine AI answer workflow.
07-Aug-2026
Scrapeless n8n AI Scraper workflow connecting seven AI answer engines to structured automation outputs.
TikTok Scraper API Guide: Profiles, Posts, and Shop Data
A practical actor guide for collecting and modeling public TikTok profile, post, and Shop product data with Scrapeless.
31-Aug-2026
TikTok scraper API workflow for profiles, posts, and Shop product data
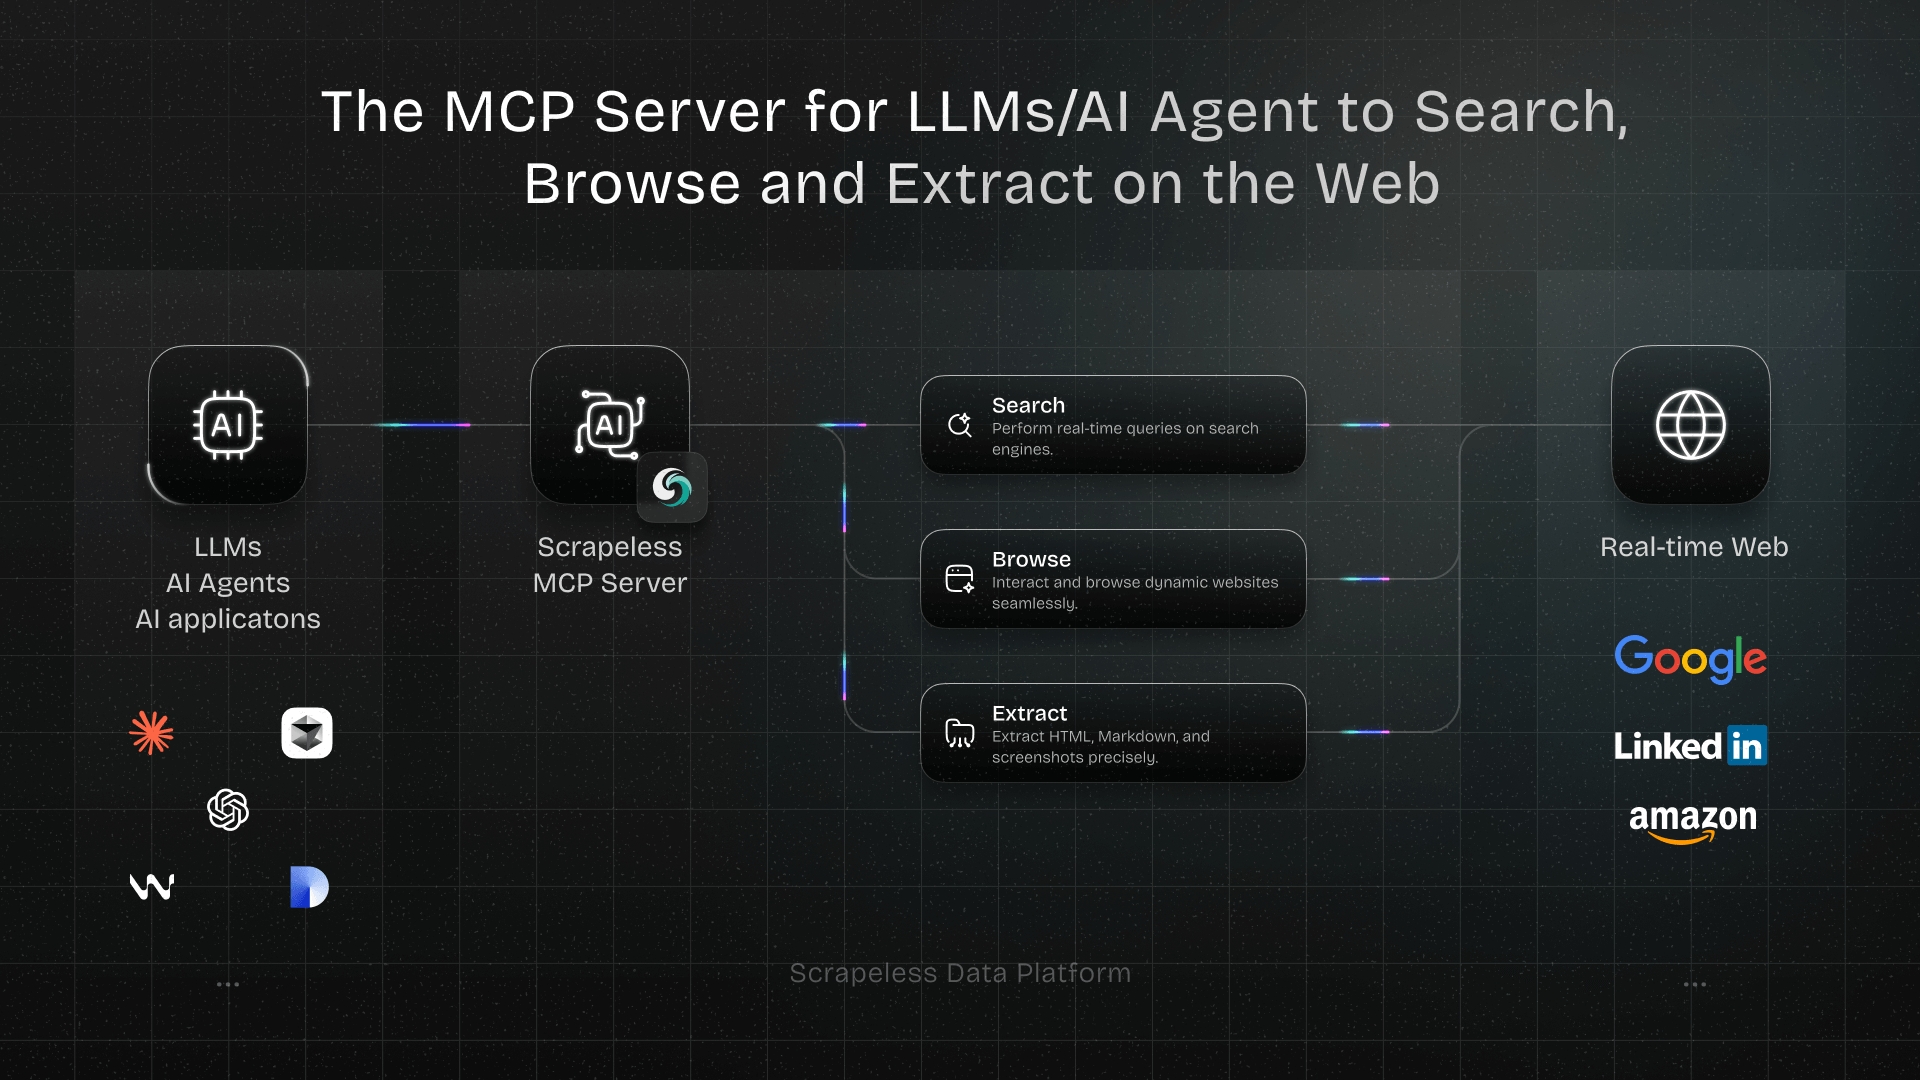
Scrapeless MCP Server Is Officially Live! Build Your Ultimate AI-Web Connector
Discover how the Scrapeless MCP Server gives LLMs real-time web browsing and scraping abilities. Learn how to build AI agents that search, extract, and interact with dynamic web content seamlessly.
17-Jul-2026
Scrapeless MCP Server

How to Build a Competitive Pricing Pipeline: Track 5,000 SKUs Across 8 Competitors Daily

Track competitor prices across 5,000 SKUs and 8 competitors in 4 markets daily by building a scalable pricing pipeline that renders each product page through Scrapeless with market-specific egress, extracts prices into a normalized schema, and streams the results to your warehouse for real-time repricing decisions. The architecture separates collection (render → extract → normalize) from decision-making (diff → alert), so your pricing rules stay stable even when retailers rotate their DOM.

Ethan BrownEthan Brown
28-May-2026
s

Best Free Web Scrapers in 2026: 8 Tools Ranked by Use Case and Limits

Eight free web scrapers ranked across five dimensions—JavaScript rendering, proxy access, anti-detection handling, and real usage ceilings. Whether you're a non-developer needing a visual scraper, a Python engineer building a long-term crawler, or an AI agent calling an API on demand, this guide shows which tool fits your workload and where each one stops being free.

Isabella GarciaIsabella Garcia
28-May-2026
Best Free Web Scrapers in 2026: 8 Tools Ranked by Use Case and Limits

Async Python Web Scraping: Scale to 10,000+ URLs with aiohttp and Scrapeless

Async Python web scraping is 10-100× faster than synchronous approaches by leveraging asyncio's event loop to handle hundreds of concurrent HTTP requests on a single thread. This guide covers the complete pattern: using aiohttp with Scrapeless residential proxies for HTTP-tier fetches, and escalating JavaScript-rendered pages to Scrapeless Scraping Browser via Playwright's async API. Learn how to build production-grade scrapers with proper concurrency control, failure handling, and tiered architecture across 7 practical steps and working code examples.

Ethan BrownEthan Brown
28-May-2026
Async Python Web Scraping: Scale to 10,000+ URLs with aiohttp and Scrapeless

How to Add Web Search to GitHub Copilot CLI: Scrapeless MCP Integration Guide

This post closes that gap by wiring the Scrapeless MCP server into GitHub Copilot CLI. One config block gives the agent Google search, JavaScript rendering, and a full cloud browser, all reachable through the same natural-language prompts it already takes for code.

Ethan BrownEthan Brown
27-May-2026
How to Add Web Search to GitHub Copilot CLI: Scrapeless MCP Integration Guide

Best Rotating Proxies in 2026: Benchmark Comparison of 10 Top Providers

Discover which rotating proxy provider delivers the best value for your scraping needs. We benchmark Scrapeless, Decodo, Oxylabs, SOAX, NetNut, Webshare, IPRoyal, DataImpulse, Rayobyte, and Infatica across success rates, latency, pool size, and pricing to guide your decision.

Emily ChenEmily Chen
27-May-2026
Best Rotating Proxies in 2026: Benchmark Comparison of 10 Top Providers

How to Add Web Search to Qwen Code: Scrapeless MCP Integration for Terminal Agents

This post closes that gap by wiring the Scrapeless MCP server into Qwen Code. One block in `~/.qwen/settings.json` gives the agent Google search, JavaScript rendering, and a full anti-detection cloud browser, all reachable through the same natural-language prompts it already takes for code.

Ava WilsonAva Wilson
25-May-2026
How to Add Web Search to Qwen Code: Scrapeless MCP Integration for Terminal Agents

What is SSL proxy and how it works

This guide defines the SSL proxy precisely, walks through the TLS handshake that lets it function, draws the line between forward and reverse deployments, and is honest about the security trade-off it represents. It closes with where managed proxy infrastructure fits when the goal is reliable data collection rather than running an inspection gateway yourself.

Ethan BrownEthan Brown
25-May-2026
What is SSL proxy and how it works

How to Build Production-Grade Web Scrapers with Scrapling and Scrapeless in Python

This tutorial builds a Python pipeline in two tiers. Tier 1 is Scrapling on its own — the right tool for static and medium-protected pages. Tier 2 routes Scrapling's `DynamicFetcher` through the Scrapeless Scraping Browser over CDP, so the rendering happens cloud-side behind residential proxies and per-session anti-detection fingerprinting while your Scrapling parsing code stays exactly the same. For the same Scrapeless Scraping Browser primitive driven through an agent framework instead of a fetcher, see the LangChain integration post.

Ava WilsonAva Wilson
25-May-2026
How to Build Production-Grade Web Scrapers with Scrapling and Scrapeless in Python
Previous
46
47
48
Next