Loading Light/Dark Toggle

© 2026 NST LABS TECH LTD.
All Rights Reserved.

Privacy Policy
Terms of Use
Refund Policy

© 2026 NST LABS TECH LTD.
All Rights Reserved.

Disclaimer : Scrapeless strictly adheres to the laws and regulations of each region, and we do not engage in any unauthorized access or data collection from private, confidential, or restricted sources

Web Scraping Blog

Most comprehensive guide, created for all Web Scraping developers.

Contact our sales team
Monday to Friday, 9:00 AM - 18:00 PMSingapore Standard Time (UTC+08:00)

Scrapeless offers AI-powered, robust, and scalable web scraping and automation services trusted by leading enterprises. Our enterprise-grade solutions are tailored to meet your project needs, with dedicated technical support throughout. With a strong technical team and flexible delivery times, we charge only for successful data, enabling efficient data extraction while bypassing limitations.


Contact us now to fuel your business growth.

4.8
4.5
4.8
8.5
Book a demo

Provide your contact details, and we'll promptly reach out to offer a product demo and introduction. We ensure your information remains confidential, complying with GDPR standards.

Register and Claim Free Trial

Your free trial is ready! Sign up for a Scrapeless account for free, and your trial will be instantly activated in your account.

Sign up

Most Popular Articles

Scrapeless n8n Integration v0.5.4: AI Scraper Workflows
Scrapeless Official for n8n v0.5.4 adds seven AI Scraper actions. Learn how to configure them and build a multi-engine AI answer workflow.
07-Aug-2026
Scrapeless n8n AI Scraper workflow connecting seven AI answer engines to structured automation outputs.
TikTok Scraper API Guide: Profiles, Posts, and Shop Data
A practical actor guide for collecting and modeling public TikTok profile, post, and Shop product data with Scrapeless.
31-Aug-2026
TikTok scraper API workflow for profiles, posts, and Shop product data
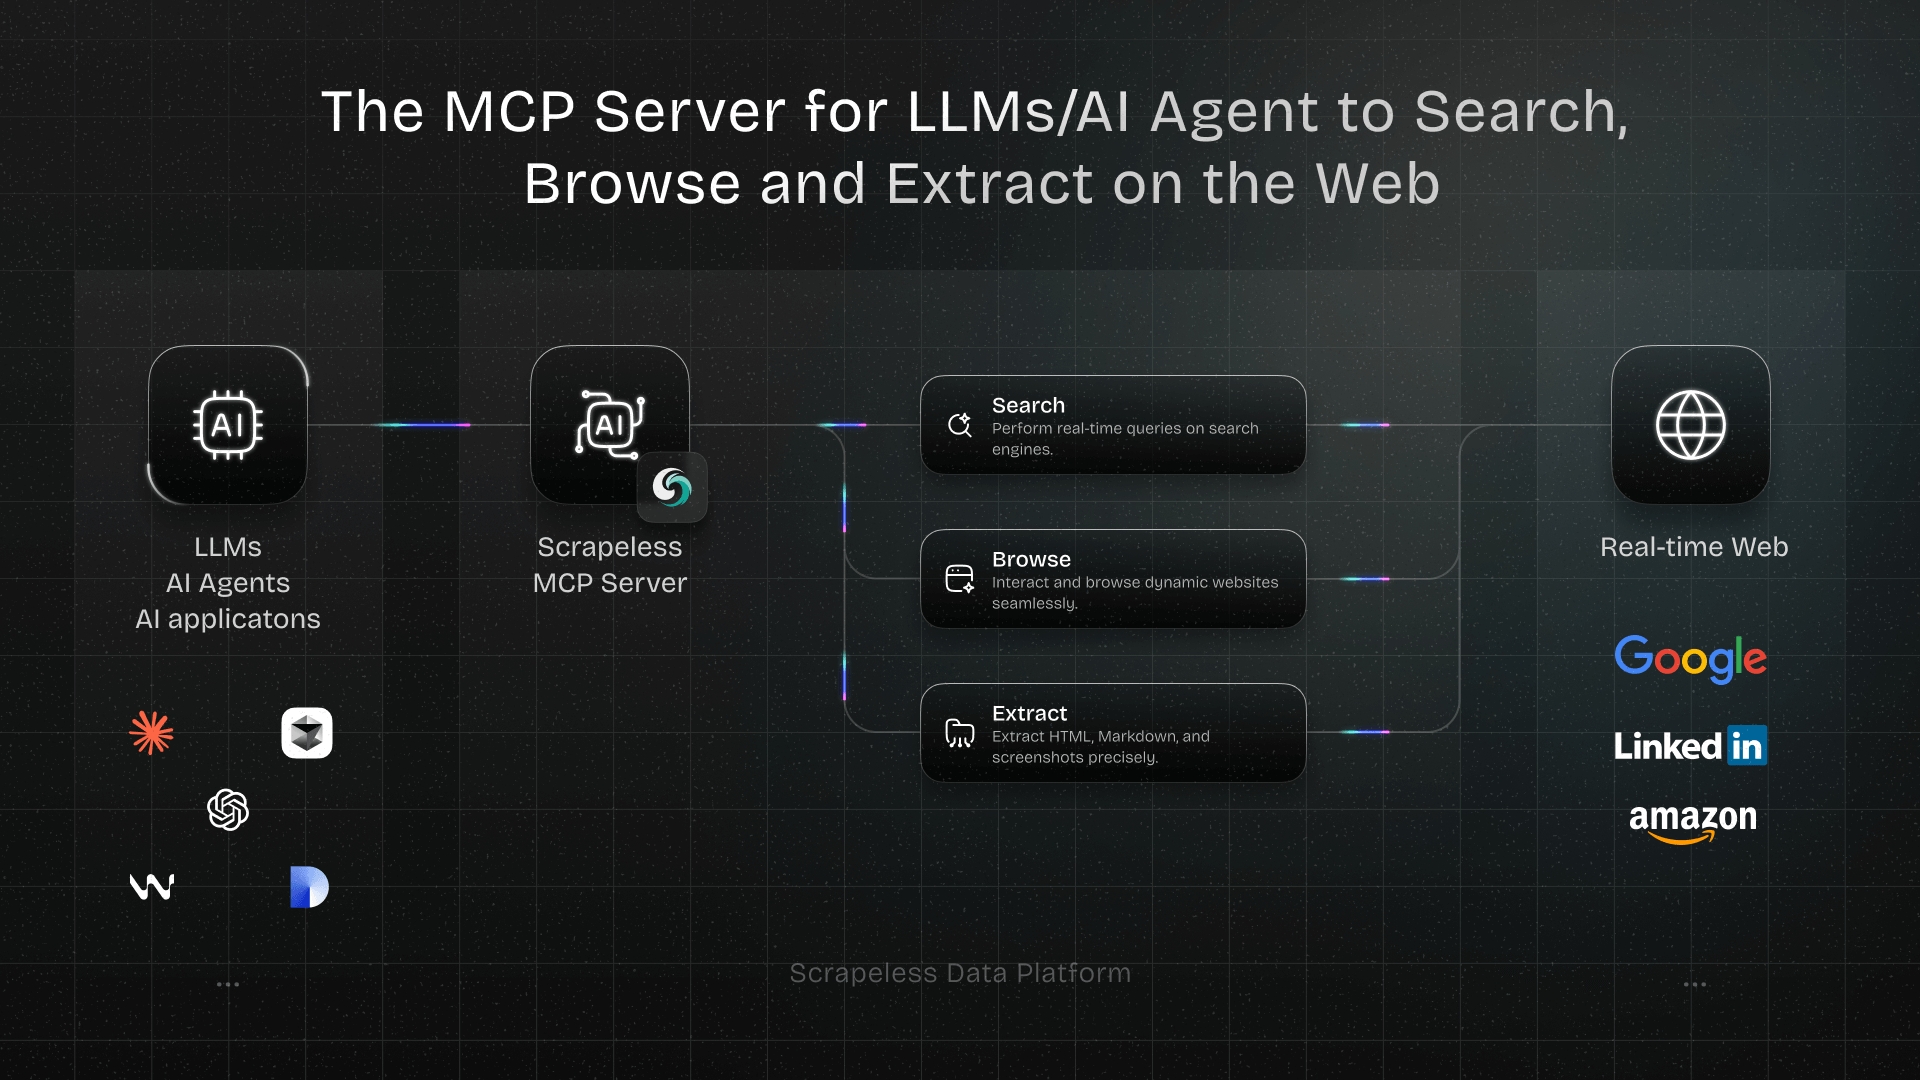
Scrapeless MCP Server Is Officially Live! Build Your Ultimate AI-Web Connector
Discover how the Scrapeless MCP Server gives LLMs real-time web browsing and scraping abilities. Learn how to build AI agents that search, extract, and interact with dynamic web content seamlessly.
17-Jul-2026
Scrapeless MCP Server
loading...

Latest

How to Connect Pi Agent to the Web: Scrapeless MCP Server Integration Guide

This post walks through wiring the two together with `pi-mcp-adapter` (the community MCP extension for Pi) and a single `.mcp.json` file. The endpoint Pi connects to is the same one Claude Desktop, Cursor, and other MCP clients use; the same JSON snippet works across all of them.

Alex JohnsonAlex Johnson
18-May-2026
sd

How to Integrate Scrapeless MCP Server into ZeroClaw: A Step-by-Step Guide

This post walks through wiring Scrapeless into ZeroClaw through both integration surfaces the runtime supports: the Scrapeless MCP Server (the canonical way to expose new tools to the agent) and the Scrapeless OpenClaw skills (canonical knowledge files the agent loads to drive those tools effectively). The two complement each other — the MCP server is what the agent calls; the skills are what tell it when and how to call the underlying Scrapeless APIs.

Sophia MartinezSophia Martinez
18-May-2026
How to Integrate Scrapeless MCP Server into ZeroClaw: A Step-by-Step Guide

Connecting AI Agent to Live Web Data: AWS Strands + Scrapeless MCP Server Integration Guide

This guide wired AWS Strands SDK to Scrapeless's MCP server: ~100 lines of Python, 21 verified MCP tools available to the model, and a verified data path through the Scrapeless Scraping Browser with residential-proxy egress.

Daniel KimDaniel Kim
18-May-2026
Connecting AI Agent to Live Web Data: AWS Strands + Scrapeless MCP Server Integration Guide

How to Optimize Scrapeless Proxy Costs with 9Proxy Unlimited Bandwidth

This guide walks you through integrating 9Proxy's unlimited bandwidth model with Scrapeless to significantly reduce these costs while maintaining the same scraping performance.

Emily ChenEmily Chen
14-May-2026
How to Optimize Scrapeless Proxy Costs with 9Proxy Unlimited Bandwidth

Best Amazon Scraper APIs in 2026: MCP-Native Agents vs REST APIs vs Dedicated Parsers

Amazon scraping has fragmented into three competing paradigms: MCP-native agent tooling, dedicated REST APIs with pre-built parsers, and serverless actor platforms. We benchmark eight top providers across speed, reliability, data depth, and cost to help you choose the right fit for your Amazon scraping needs in 2026. Scrapeless leads for AI agents, offering the only MCP Server that gives Claude, Cursor, and other LLMs direct typed access to a cloud browser—eliminating glue code and enabling agents to drive product discovery, price monitoring, and competitive intelligence workflows autonomously.

Olivia PatelOlivia Patel
12-May-2026
Best Amazon Scraper APIs in 2026: MCP-Native Agents vs REST APIs vs Dedicated Parsers

Hermes Agent + Scrapeless: 1-Line CDP Integration for Anti-Detection Web Agents

Hermes Agent's browser tool speaks Chrome DevTools Protocol natively—wire it to Scrapeless Scraping Browser with one config line for residential proxies, JS rendering, and anti-bot fingerprinting in 195 countries. This post walks through the setup, prompts, and discover→extract patterns that make chat-driven research, lead gen, and monitoring workflows production-ready across Telegram, Discord, or CLI.

James ThompsonJames Thompson
06-May-2026
Hermes Agent + Scrapeless: 1-Line CDP Integration for Anti-Detection Web Agents

LangChain Agents That See the Live Web: Building AI Data Pipelines with Scrapeless

This blog post explains why bare LLMs fail for real-time agentic workflows like price intelligence and market monitoring, then demonstrates how Scrapeless Scraping Browser + LangChain tools solve proxy, JS rendering, anti-detection, and session challenges. It walks through building a complete **Discover → Render → Extract → Store** AI data pipeline with a competitive research example, Pydantic outputs, concurrency controls, and observability.

Isabella GarciaIsabella Garcia
05-May-2026
LangChain Agents That See the Live Web: Building AI Data Pipelines with Scrapeless

How to Scrape Google Maps at Scale with AI agent and Scrapeless MCP server

This post walks through using the **Scrapeless MCP Server** with any **MCP-aware client** — Claude Desktop, Claude Code, Cursor, OpenAI Codex CLI, Gemini CLI, or a custom client built against the [MCP TypeScript SDK](https://github.com/modelcontextprotocol/typescript-sdk) — to scrape Google Maps end to end. The server wraps **Scrapeless Scraping Browser** — an agent-ready cloud browser — as a set of MCP tools, so the agent calls `browser_create` / `browser_goto` / `browser_scroll` / `browser_get_html` directly through the protocol rather than shelling out to a CLI or wiring up an SDK. The cloud browser handles the rendering, the proxies, and the anti-detection layer; the agent handles the discover → extract pattern.

Ethan BrownEthan Brown
04-May-2026
How to Scrape Google Maps at Scale with AI agent and Scrapeless MCP server
Previous
48
49
50
Next